


Research project Språkbanken
Språkbanken is a national consortium that develops and distributes infrastructure for research that makes use of language data (speech, sign, text).
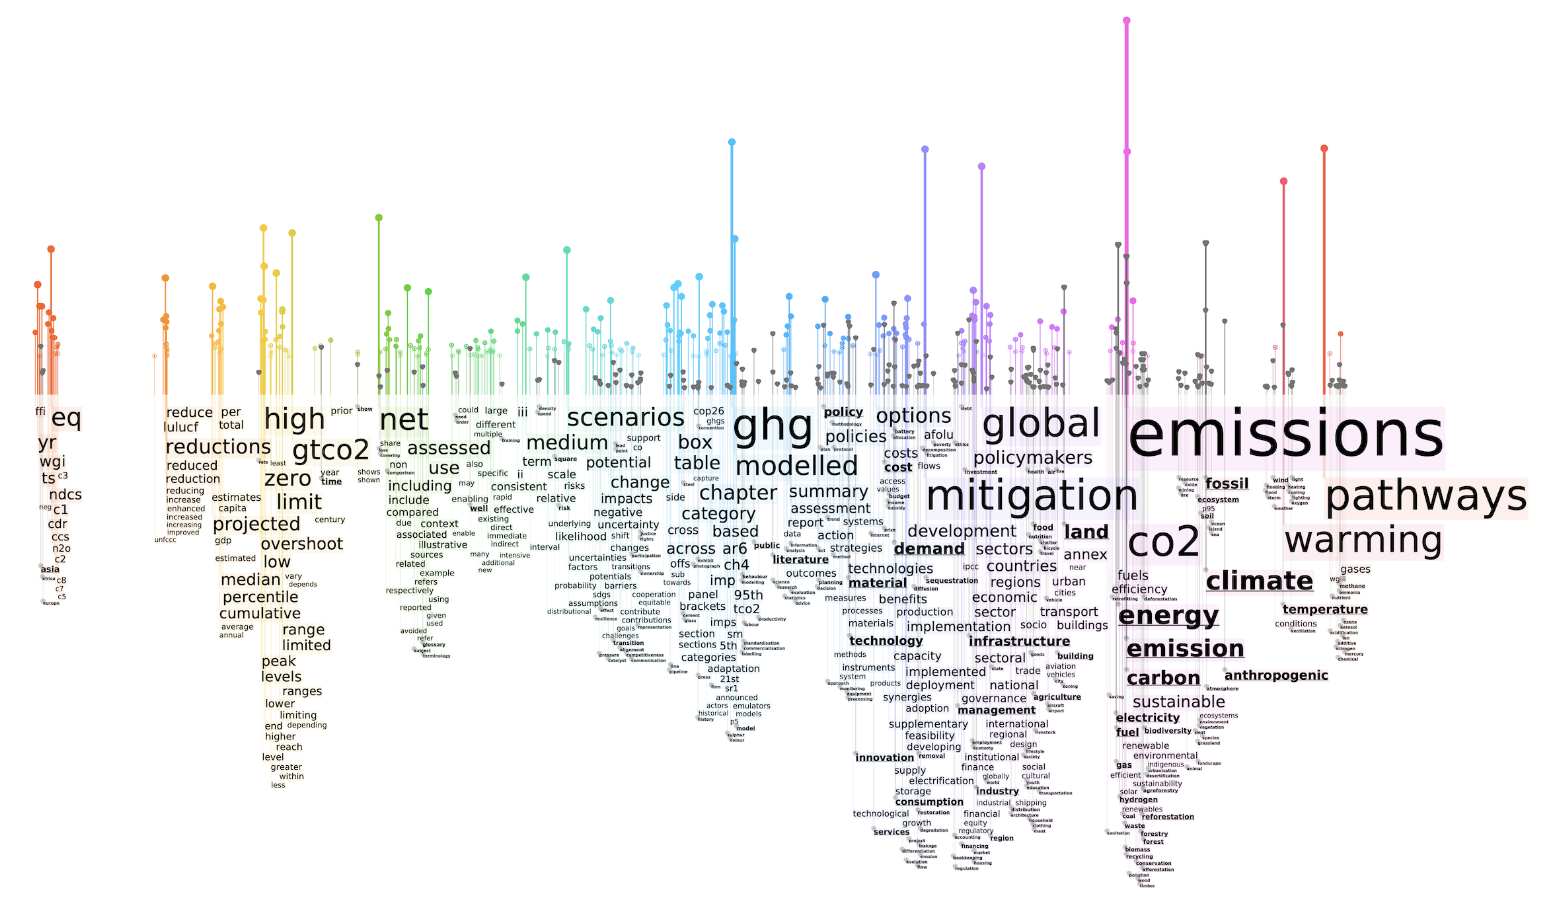
Illustration: wordrain.org
Infrastructure here means tools and datasets that are ready-made and openly available, allowing researchers to spend more time on the actual research. Stockholm University participates in Språkbanken through the Computational Linguistics and Sign Language sections at the Department of Linguistics.
The consortium was launched in 2014 and is jointly funded by the Swedish Research Council (VR) and the ten participating universities and memory institutions. Språkbanken is part of the EU consortium CLARIN, which provides research infrastructure for linguistic data at the European level.
Activities in Computational Linguistics center on the development of research infrastructure for text data, primarily in Swedish and for multilingual parallel texts:
- Tools for the morphosyntactic analysis of Swedish text
- Tools for aligning and processing parallel texts
- Tools for visualizing text collections, for example using word rains
- Datasets and tools for the development and evaluation of large language models as well as grammar-checking systems
- Datasets for research in writing development, writing support and linguistic typology
Activities in Sign Language center on the development of resources used by researchers as well as in teaching and by the general public:
ORGANISATION:
Computational Linguistics: Robert Östling, Beáta Megyesi, Moa Gärdenfors and Maria Skeppstedt
Sign Language: Krister Schönström, Mats Wirén, Dag Lindeberg, Nikolaus Riemer Kankkonen and Josefin Bark
(See contact details below.)