


Looking into the black box – new tool reveals how AI constructs its answers
Chatbots hallucinate – we all know that. And we’re also aware that AI can use information from sketchy websites to produce its answers. DSV researchers have developed a tool to deal with some of the trust issues.
When you ask Chat GPT, Claude, Gemini or Perplexity a question, it answers quickly and confidently. But how do you know that the answer is based on the best sources?
Korbinian Randl, PhD student at the Department of Computer and Systems Sciences (DSV), is determined to improve the trustworthiness of large language models – LLMs – which chatbots rely on.
“When I’m talking to people in my social circles, I get the feeling that they humanise LLMs a lot. That has to do with how the chatbots are designed of course – they make you feel like you’re talking to another human. We are also used to computers being right all the time. But AI can fail, and I think we need methods to show that”, says Korbinian Randl.
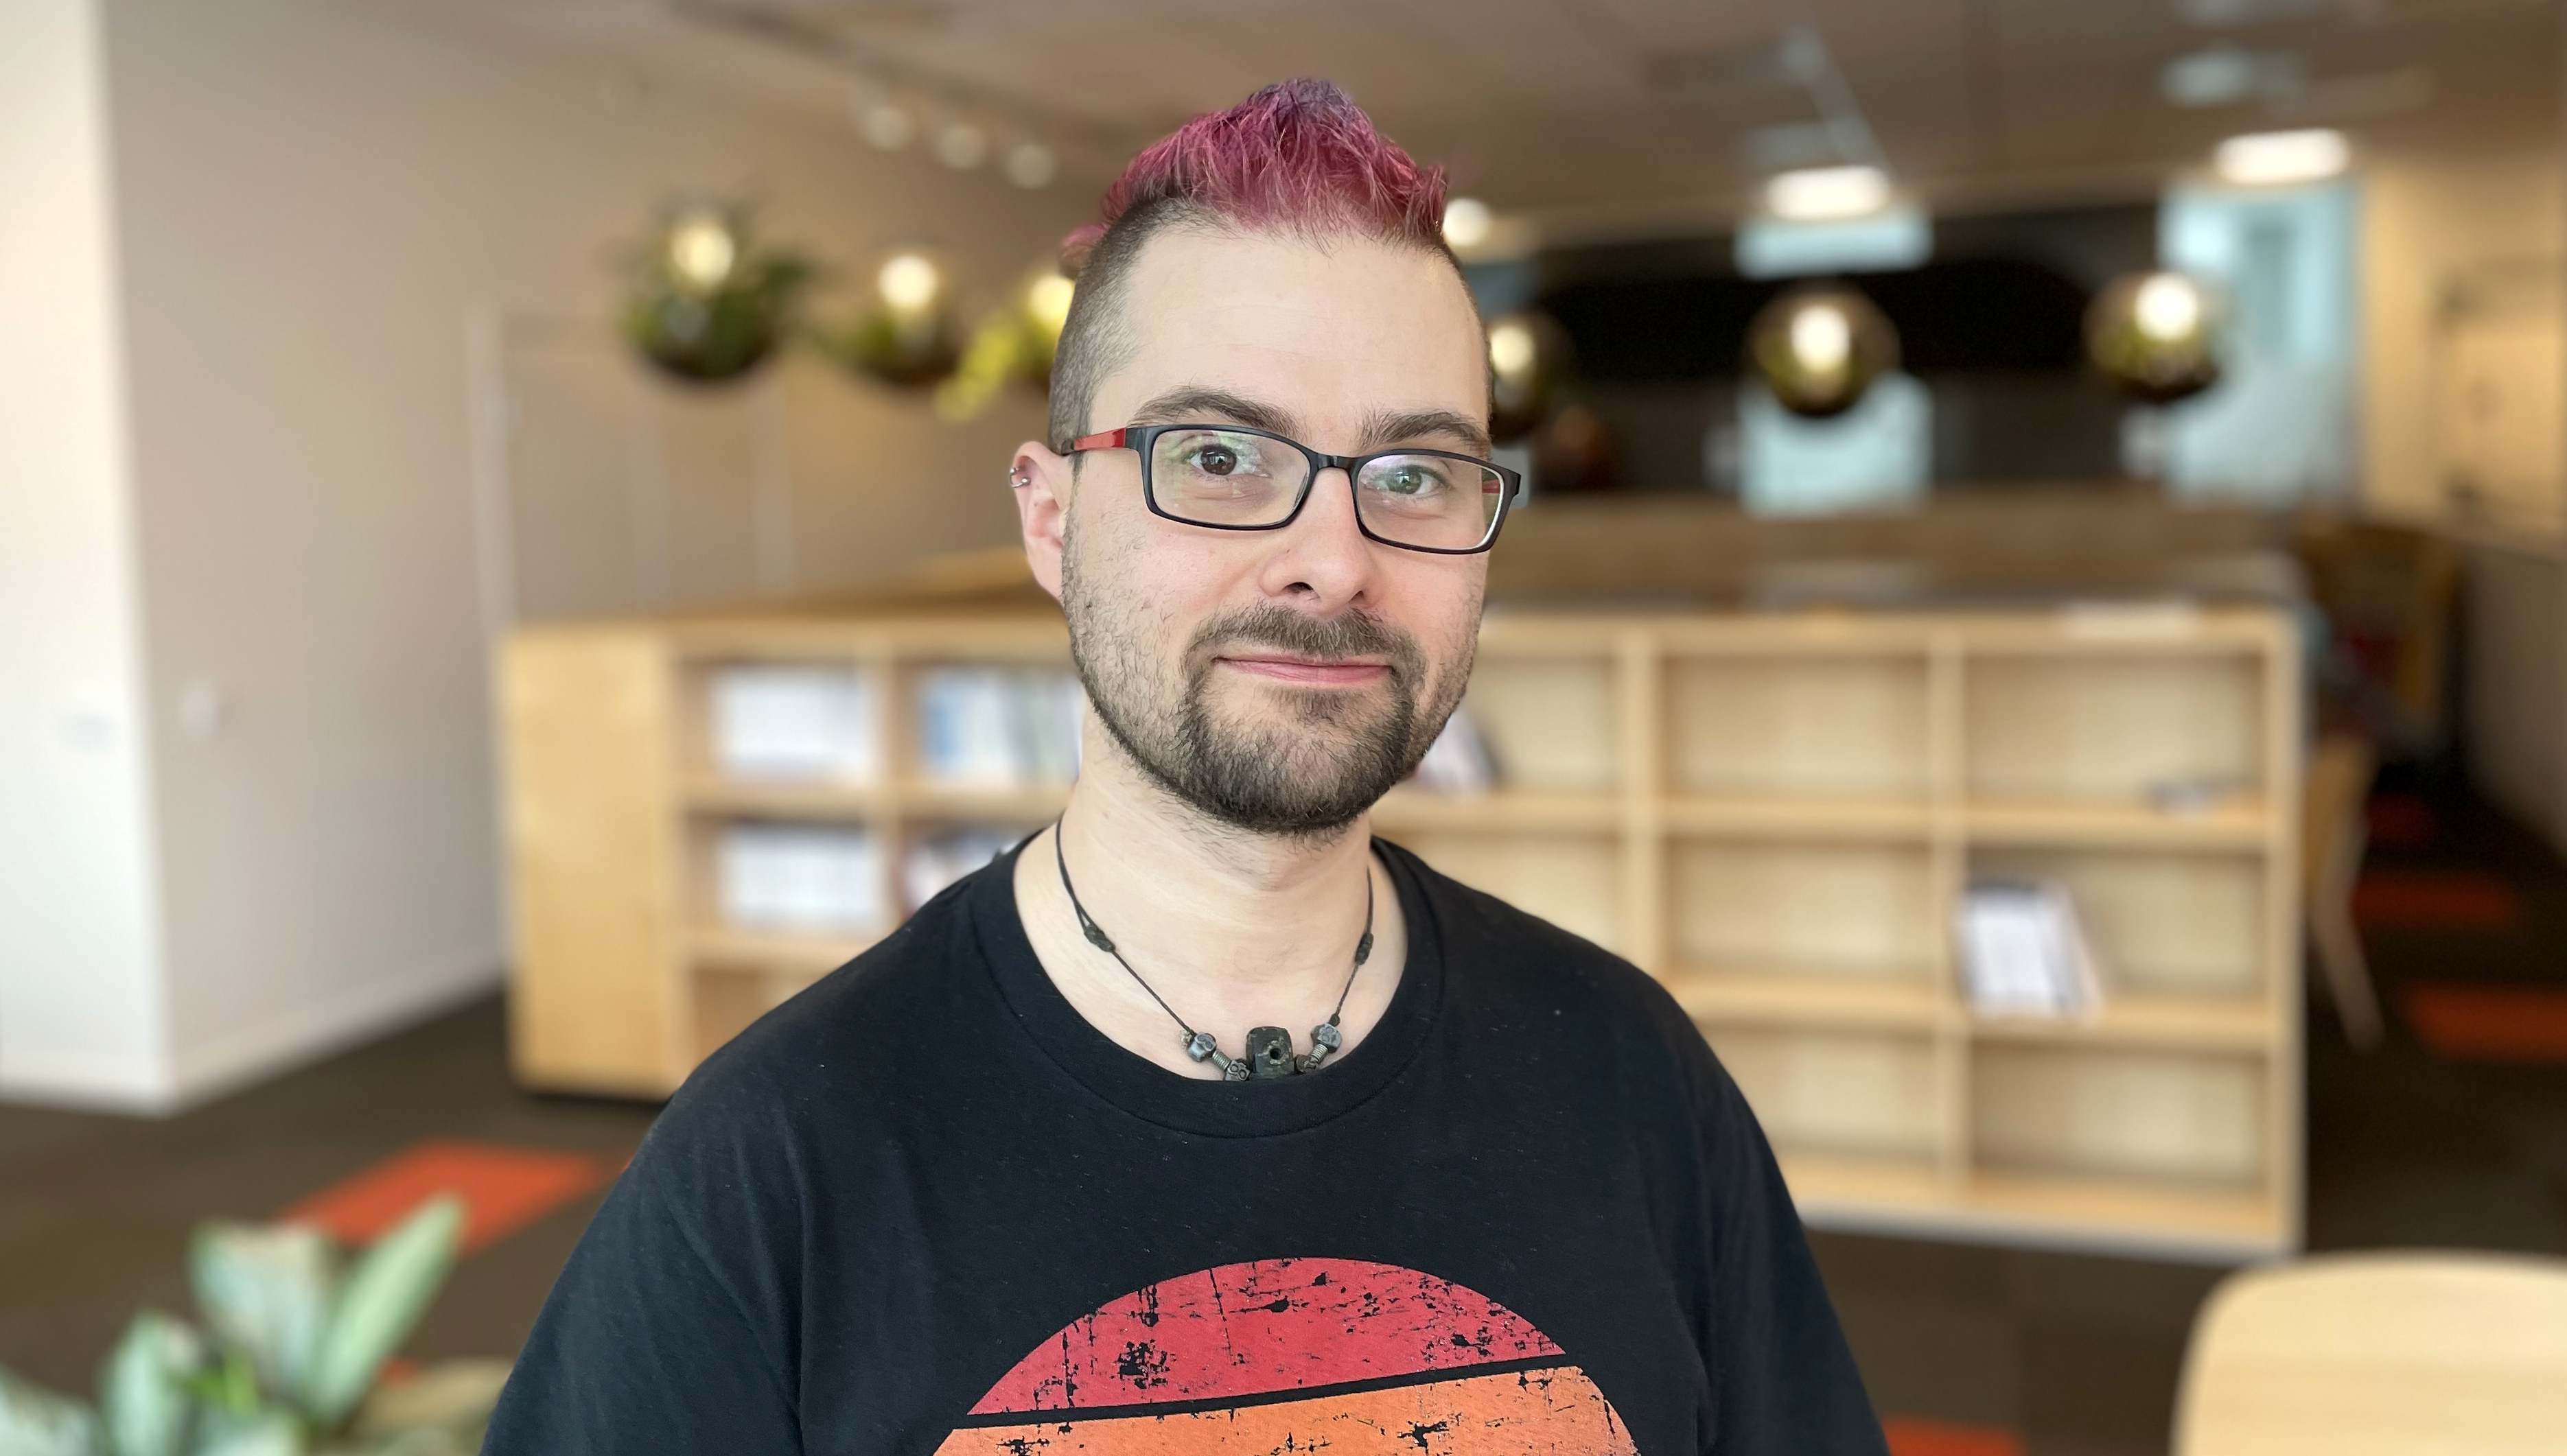
Explainability is key if we should be able to trust AI. Korbinian Randl explores the topic in his research.
Two components kick in when you send a prompt to your chatbot. First, a retriever module searches websites and other sources, and ranks documents by relevance to the query. Then the generator, a large LLM, reads those documents and writes an answer. This is called the RAG system (Retrieval-Augmented Generation).
A scientific paper – and a working tool
The tricky part is that both of these components can fail. And you don’t know if the chatbot uses relevant documents within the pool of retrieved documents to write its answer, or if it’s relying on Reddit threads. In fact, there is often a gap between the retriever’s ranking and the sources that the generator actually uses. But this problem has now been addressed by Korbinian Randl and his research colleagues.
“We have created a framework that highlights which parts of the documents were used to generate the ranking. It also highlights which parts of the documents were used to generate which parts of the output.”
“We’ve written a scientific paper about this, but we’ve also built a working tool”, Randl explains.
His studies show that generators ignore retrievers’ top-ranked documents up to 78% of the time. And when retriever and generator do agree, the chatbot’s answers are up to four times more likely to be correct.
The models are not thinking
If you’re just asking Chat GPT about dinner recipes, or a celebrity’s love life, maybe the sources are less important. But if you’re a medical doctor consulting an AI system to help a patient, it is crucial that high-quality documents are used to generate the best answer. Transparency, explainability and trust are essential in this process.
“AI models generate natural language through a statistical process, by predicting which word is most likely to follow. The models are not thinking, and they are not logical. There are a lot of insecurities here,” says Korbinian Randl.
“This is why we need explainability. We need to be able to explain each answer so that the user can understand what the model focused on internally,” he continues.
Randl also points out that users have a right to an explanation, according to the EU’s General Data Protection Regulation (GDPR).
Addressing the gap in a new way
He and his colleagues call their new auditing framework RAG-E. Besides explaining why documents were retrieved and how much they influenced the generated answer, RAG-E combines the two into a single alignment score – WARG.
“The idea of a gap between what the retriever lists and what the generator uses – and explaining such systems – is not new. Other researchers have written papers about this, focusing on one of the components. But I have not been able to find existing literature that combines the processes of receivers and generators. So in that sense, this is new-to-the-world findings.”
Developers of AI models can put the new framework to the test by importing it to their source code. By changing two lines of code, they get access to their WARG score and the explanation behind it.
The models are designed to always produce answers
But for users of generative AI tools like Chat GPT, the process behind the answer is still hidden – at least for now. So what can we do to protect ourselves from hallucinations and misleading answers?
“My sad answer to the question is to always double-check. Google it!”
“Alignment between receivers’ lists and generators’ answers depends on so many things: the topic, the model you use, how you phrase the question – and also luck. The models are designed to always produce answers and never talk up to you,” says Korbinian Randl.
More about the research
The paper “Quantifying Retriever-Generator Alignment in RAG with Local Explanations” has been accepted to the 2026 Conference on Empirical Methods in Natural Language Processing (EMNLP). It will be presented in Budapest, Hungary on 24–29 October.
The paper is written by Korbinian Randl (DSV, Stockholm University), Guido Rocchietti (TU Berlin), Aron Henriksson (DSV, Stockholm University), Ziawasch Abedjan (TU Berlin), Tony Lindgren (DSV, Stockholm University) and John Pavlopoulos (Athens University of Economics and Business).
Read the preprint
Read a blog post by Korbinian Randl
Korbinian Randl is a PhD student at the Department of Computer and Systems Sciences (DSV), Stockholm University.
Contact Korbinian
More about DSV’s research and education
Last updated: 2026-10-06
Source: Department of Computer and Systems Sciences